Data mapping, normalization, transformation and orchestration, built in your own cloud, on AWS, Databricks or Azure. No rip-and-replace.
It sits in EHRs, legacy platforms, HL7 feeds, flat files, vendor databases and portals. Every analytics, AI, research or compliance project begins with months of manual integration work, and the result is often brittle, hardcoded and expensive to maintain.
Replacing the system is rarely the answer. Unlocking the data is.
Source-to-target mapping across HL7 v2, FHIR, flat files, databases and APIs, with code set crosswalks for ICD, CPT, LOINC, SNOMED CT and local codes.
Cleaned, standardized and de-duplicated records, with data quality rules at every stage.
Raw feeds converted to FHIR, OMOP and analytics-ready models, in a layered bronze, silver and gold structure.
Scheduled and event-driven pipelines with monitoring, retries and audit trails, delivering data to your warehouse, your applications and, through ConnectHealth, back into your EHR where the EHR allows it.
Unlock data from older EHRs, billing, lab and claims platforms without replacing them. We connect, map and normalize it into a modern, governed data layer.
Best for: community and rural hospitals, post-acute and behavioral health, labs, payers and TPAs, health IT vendors.
Bulk FHIR and API extraction from Epic, Oracle Health, MEDITECH and other major EHRs into your own S3, Delta Lake, Redshift or Snowflake environment. PHI stays in your environment.
Best for: providers, digital health companies, payers.
Automated FHIR-to-OMOP pipelines with vocabulary management and validation, producing standardized research databases for cohort analysis, studies and AI/ML.
Best for: life sciences companies, academic medical centers, research organizations.
Event-driven pipelines retrieve charts, route them to clinical NLP and review tools, and load validated results into your warehouse for HCC, quality and gaps-in-care workflows.
Best for: value-based care organizations, health plans, risk-bearing provider groups.
Governed, structured clinical data prepared for your own models and agents, in your own cloud.
Best for: organizations building analytics or AI on clinical data.
Most data platforms stop at analytics. With ConnectHealth, risk scores, care gaps and follow-up flags can be written back into the EHR where the EHR allows it, closing the loop between data and care delivery.
Best for: customers whose EHR allows write-back and who want insight to change care workflows.
Pull data from EHRs, portals, files and databases, in bulk or in real time.
Event-driven workflows route each record to the right processing step.
Map, clean and standardize into a governed model: FHIR, OMOP or your own schema.
Quality checks at every stage, with reports your teams can trust.
Load to your lake or warehouse, and write results back to source systems, including the EHR where it allows it.
Pipelines run inside your own cloud account.
Patient data reached a financial-assistance network's platform through manual Excel uploads, and specific records had to be requested from providers. Mindbowser built an automated connection to Epic.
The organization wanted to automate chart retrieval and risk adjustment end to end. Mindbowser designed the integration and orchestration layer.
Health assessments arrived as PDFs and scanned images, so their data stayed out of reach until someone read and retyped it. Mindbowser built a serverless AI ingestion pipeline on AWS.
Deployed in your own cloud.
The code we write, the mappings and the documentation are yours.
Deep experience with EHR integration, FHIR and clinical code sets.
Infrastructure as code, automated vocabulary updates and quality checks at every stage.
Write-back into the EHR through ConnectHealth, where the EHR allows it.
A data assessment and mapping sprint on one source system. You get a documented mapping specification whether or not you continue.
Pipelines, normalization and your first use case in production. Larger programs run in phases with quality gates.
Managed orchestration, monitoring, new source onboarding and support.
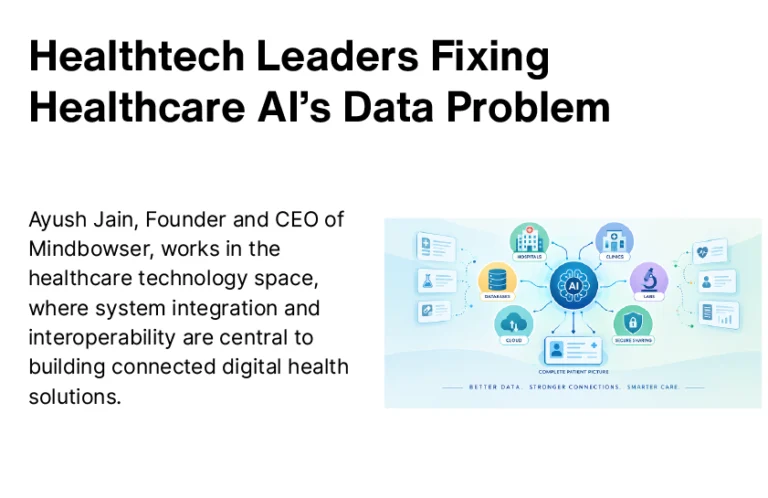
Healthcare data integration brings data from many systems into one consistent form, so people and software can use it. That means pulling records from EHRs, labs and billing platforms, matching them to the right patient, mapping local codes to standard ones, and loading the result where your teams can query it.
Healthcare data orchestration is the part that keeps it running: scheduled and event-driven pipelines, retries, monitoring and audit trails. Our guide to how EHR data integration works covers the methods.
| Data type | What it holds | Usual formats |
|---|---|---|
| Clinical | Encounters, problems, medications, allergies, notes and orders | FHIR, HL7 v2, C-CDA |
| Lab and diagnostic | Results and reference ranges, coded in LOINC or local codes | HL7 v2 |
| Imaging | Studies and their metadata | DICOM |
| Device | Readings from remote monitors and wearables | Vendor APIs |
| Claims and payer | Claims, remittances and rate files, often joined to clinical data for risk adjustment | X12, flat files |
| Referral and social | Referrals between care settings and social determinants of health (SDOH) records | Files and APIs |
Each type arrives in its own format, on its own schedule, with its own quality problems. Integration resolves those differences in one place, so every report and model starts from the same data.
AI unlocks the data work, ConnectHealth unlocks EHR access, and Mindbowser builds both.
| Job | What AI does | What your people keep |
|---|---|---|
| Mapping | Drafts source-to-target mappings | Your data team approves each one |
| Documents | Turns PDFs, faxes and scans into fields, each with a confidence score | A person on your team checks low-confidence values |
| Patient matching | Suggests likely matches | Your health information team decides in a review queue |
| Plain-language questions | Writes read-only SQL over a governed layer, and shows the query beside the answer | Your team defines the metrics |
| De-identification | Finds identifiers across notes and images at scale | Your privacy officer approves each release; a qualified expert makes any Expert Determination |
| Labeling | Pre-labels images and text | Your clinicians correct the labels |
EHR vendor approvals, data rights, BAAs, consent and clinical ground truth stay with the people who hold them today.
A health system may run one EHR in its hospitals, another in its clinics and a third in an acquired practice. A digital health company may connect to many customer EHRs.
We build one data layer above them. Each source keeps running. Its data maps to one shared model, so a patient, a medication or a lab result is recorded the same way whichever system it came from. Once a new source is connected, it needs one new mapping.
For a behavioral health network, we brought seven sources into one patient view with 15 clinical and operational cards.
Connecting to each EHR is its own job. Our EHR integration and interoperability services cover that side. We help you through each EHR vendor's partner or API application; approval stays with the vendor and the practice.
Integration gets data into one place. Data management keeps it trustworthy: who owns each dataset, how changes are tracked, how long data is kept and who can see what.
Your governance council owns those decisions. We build the technical side into your pipelines: a source inventory, lineage, role-based access and audit logs.
Master data keeps core records consistent: patients, providers, locations and payers. We set up the matching rules and reference tables that give each one a trusted record. For patients, we build a review queue for your health information team and an enterprise ID across systems, or we integrate the commercial EMPI you license.
Quality checks run at each stage of the pipeline, so problems surface where they start.
| Problem | What it causes | What we build |
|---|---|---|
| Duplicate patients across systems | Split histories, wrong counts | Matching rules and a review queue |
| Local and outdated codes | Records you can't compare | Mappings to LOINC, RxNorm, SNOMED CT, ICD-10 and CPT, automated vocabulary updates, and a review queue for unmapped codes |
| Inconsistent units and formats | Wrong values in analysis | Normalization rules, with the original value kept beside the new one |
| Silent feed failures | Stale data nobody notices | Monitoring, retries and a reconciliation report on every load |
A healthcare data integration strategy starts small and proves itself on one source. These are the practices we build to.
We pick the approach by what each source supports and how fresh the data needs to be.
| Approach | When it fits |
|---|---|
| HL7 v2 feeds | Real-time clinical events from hospital systems |
| FHIR APIs | Specific records and apps |
| Bulk FHIR export | Large scheduled extracts, where the EHR enables it |
| X12 transactions | Claims and eligibility data, mapped through ConnectHealth |
| Database and flat-file extracts | Legacy systems without modern APIs, and extracts your EHR team produces |
| C-CDA documents | Referral notes and discharge summaries, turned into structured FHIR through ConnectHealth |
| HIE connections | ADT feeds, document query and Direct messaging |
| Portals and documents | Data held in external portals or PDFs |
| Public web data | Published files and registries, within each site's terms. Never a route to EHR data |
For hospital feeds, our HL7 v2 integration work covers interface setup. ConnectHealth data mapping handles HL7 v2, X12 and FHIR formats. ELT usually fits cloud platforms such as Databricks, Snowflake and Redshift, where transformation runs inside the platform.
We build HIPAA safeguards into every pipeline and work under a signed BAA. Mindbowser is SOC 2 Type II audited.
Your privacy and compliance teams set the rules. We build the controls in your own cloud: role-based access, audit logging, retention jobs, and de-identification before data is shared.
Mindbowser is an Epic Vendor Services member and an AWS Advanced Tier Partner.
We build your healthcare data integration platform in your own AWS, Azure or Google Cloud account. At the end of the build you own the code we write for you, the mappings, the data model, the documentation and your data; ConnectHealth, our product, is licensed.
ConnectHealth is our EHR integration product. It handles EHR access, bulk FHIR export, HL7 and X12 feeds, mapping, workflow and write-back where the EHR allows it. Your team can run it, or we build with it.
After go-live you choose: we run the pipelines, or we hand over the code and documentation.
One approach serves different starting points.
| You are | What usually comes first | Where we start |
|---|---|---|
| A digital health or AI company | Clean EHR data inside your product | One customer EHR, mapped to your model |
| A health system or provider group | One view across the systems you already run | One source, loaded to your warehouse |
| A medtech or life sciences company | Data ready for models and research | One dataset. For a remote endovascular-robotics company, we cut DICOM processing from weeks to a day |
It depends on scope. The assessment covers one source system, and the scope it produces sets the build. Larger programs run in phases with quality gates.
You do. You own the code we write for you, the mappings, the data model, the documentation and your data. ConnectHealth, our product, is licensed.
Pipelines run in your own cloud account. With ConnectHealth, AI steps stay in your cloud when you use a model in your own account. With an outside model, the optional Guardrails step redacts identifiers from the text before it's sent.
Epic, Oracle Health, MEDITECH and other major EHRs, plus HL7 v2 feeds, flat files, portals and vendor databases.
ConnectHealth gets the EHR data in and acts on what your data shows. We build the lake and what makes its data trustworthy. Many programs use both. ConnectHealth has full FHIR read and write on Epic, Oracle Health (Cerner) and MEDITECH, and Unity writes on Veradigm. On athenahealth, eClinicalWorks and Elation it reads, and Mindbowser builds the write path on each vendor's own write APIs. AdvancedMD, Healthie and TouchWorks are read-only.
A documented mapping specification for one source system, whether or not you continue. The assessment starts under a signed BAA where PHI is involved, and you can take the plan to another builder.
It depends on what you connect. Talk to us and we'll scope it from your sources.
You'll have a documented mapping specification for one source system, whether or not you go further.
Book a data assessmentPartner with us to design, build, and scale digital solutions that drive better outcomes.
Global Tech Teams LLC, 525 Washington Blvd, Industrious at Newport Tower, Jersey City, NJ 07310, United States.
Let’s discuss your goals, workflows, and next steps in a focused consultation call.
 Schedule a Call






 BLOGS
 NEWSROOM
 CASE STUDIES
 WEBINARS
 PODCASTS
 ASSET HUB
 EVENT CALENDAR